| Training | Inference |
|---|---|
| What it does | Finds the weights |
| How often | Once, over weeks or months |
| Hardware | Tens of thousands of processors, tightly coupled |
| Cost shape | A large one-time capital cost |
Training is the process of finding a model's weights from data. For a frontier model it means tens of thousands of processors working as one machine for months. That is the figure usually quoted, and it is a real one. Then it ends.
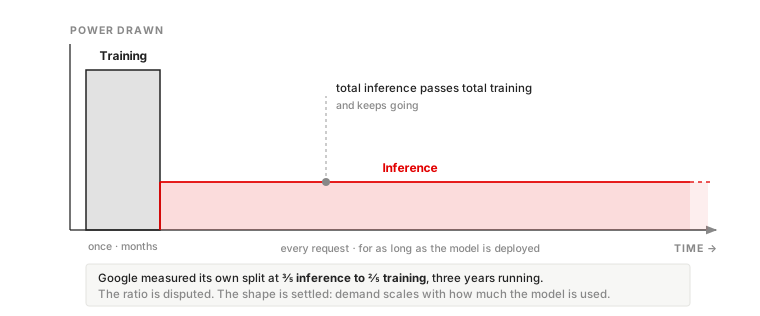
Inference is using the finished model. Each answer is cheap, and the answers never stop: every request, every day, for as long as the model is in service.
Why this decides data-center demand
Google measured its own machine-learning energy for one April week in each of 2019, 2020, and 2021. About three-fifths was inference and two-fifths training, with machine learning at 10 to 15% of the company's total energy in those weeks. The CPU share of inference was estimated from profiling and may be high. Measured and partly estimated.
The exact ratio is contested and moving. The shape is settled. Training is bounded and ends; inference begins at deployment and continues. So demand grows with use, and what gets run, and how often, stays a lever for as long as a system is deployed.
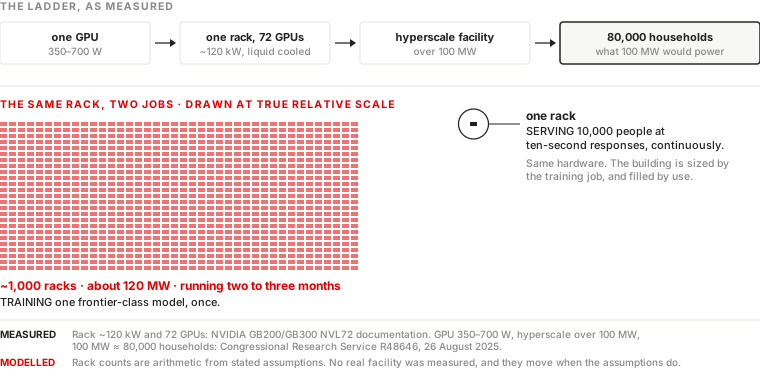
Two questions get collapsed here. How large a facility has to be is set by training, a single job that needs a great many machines at once. How much that facility draws across its life is set by use. An argument that answers one while claiming to settle the other is the most common error in this debate.
What a query actually costs
Per-query energy is smaller than most headlines suggest. A 2026 peer-reviewed study, using production serving assumptions, puts a frontier-model query at a median of 0.31 watt-hours and finds widely cited estimates overstate it by 4 to 20 times. The same work finds long reasoning queries raise that median roughly thirteenfold, so the pressure runs both ways at once.
What this means for an organization using AI
Because inference is the permanent cost, the choices that matter most are made after deployment: which model handles which task, how often it is called, and whether a smaller model would do. Routing each task to the smallest model that does it well is one of the largest levers on both cost and energy.
Sentinel, an AI gateway, measures each request and shows it in the account, one way to watch inference use as it happens for the prompts it handles.
Frequently asked questions
- Which uses more energy over a model's life?
- Inference is the larger and permanent load. Training is bounded and ends, while inference begins at deployment and continues for as long as the model is in service. In Google's measured weeks in 2019, 2020, and 2021, about three-fifths of its machine-learning energy was inference and two-fifths was training. The exact ratio is contested and moving.
- How large a data center is needed, and how much does it draw?
- Two questions get collapsed here. How large a facility has to be is set by training, a single job that needs a great many machines at once. How much that facility draws across its life is set by use. An argument that answers one while claiming to settle the other is the most common error in this debate.
- How much energy does a single AI query use?
- Less than most headlines suggest. A 2026 peer-reviewed study, using production serving assumptions, puts a frontier-model query at a median of 0.31 watt-hours and finds widely cited estimates overstate it by 4 to 20 times. The same work finds long reasoning queries raise that median roughly thirteenfold, so the pressure runs both ways.
- Is inference really 80 to 90% of AI energy?
- We could not find a primary source for that range. Google's one-week measurements are the scoped figure that holds: about three-fifths inference to two-fifths training, measured and partly estimated. The shape is settled, since training ends and inference continues, but the exact ratio is contested and moving.
- What can an organization do to control inference costs?
- The choices that matter most are made after deployment: which model handles which task, how often it is called, and whether a smaller model would do. Routing each task to the smallest model that does it well is one of the largest levers on both cost and energy, for as long as a system is deployed.
Keep going
Does all AI need a hyperscale data center?
What is a model weight, and what is a transformer?
Reading an AI contract?
A practical next step
For regulated work
Sources
- Patterson, Gonzalez, Hölzle, et al., The Carbon Footprint of Machine Learning Training Will Plateau, Then Shrink, IEEE Computer, 2022.
- Oviedo, Kazhamiaka, Choukse, et al., Energy Use of AI Inference, Efficiency Pathways, and Test-Time Scaling, Joule, 2026.
- International Energy Agency, Energy and AI, April 2025. Data centers at about 415 TWh in 2024, roughly 1.5% of global electricity, projected to about 945 TWh by 2030.
- NVIDIA documentation for GB200 and GB300 NVL72 rack power envelopes: approximately 120 kW and 135 kW respectively.